LongCat-Video
Meituan · Video Generation & Multimodal Pretraining
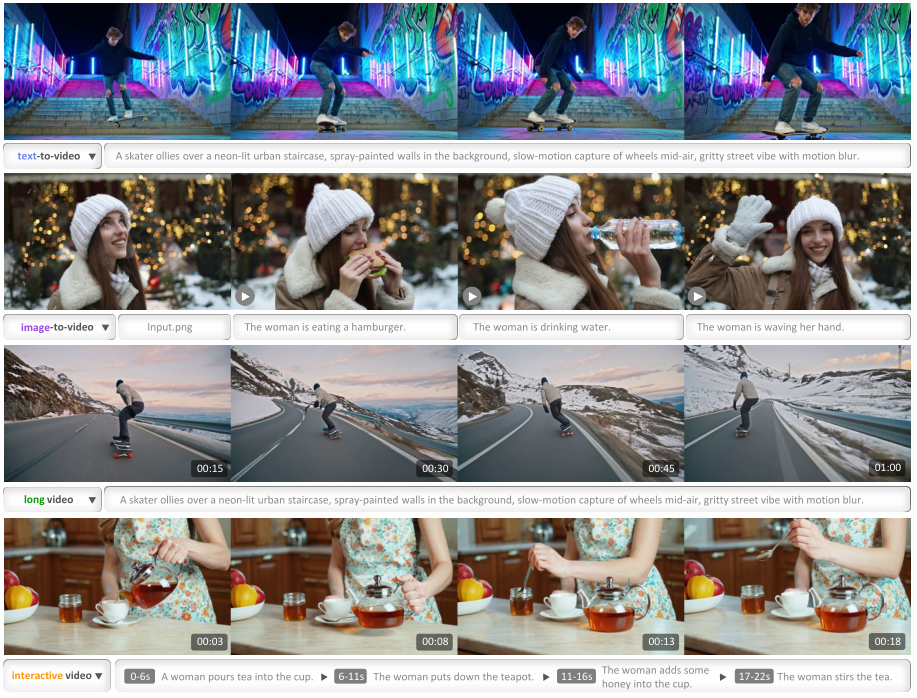
LongCat-Video is Meituan's unified foundation model for text-to-video, image-to-video, and video continuation.
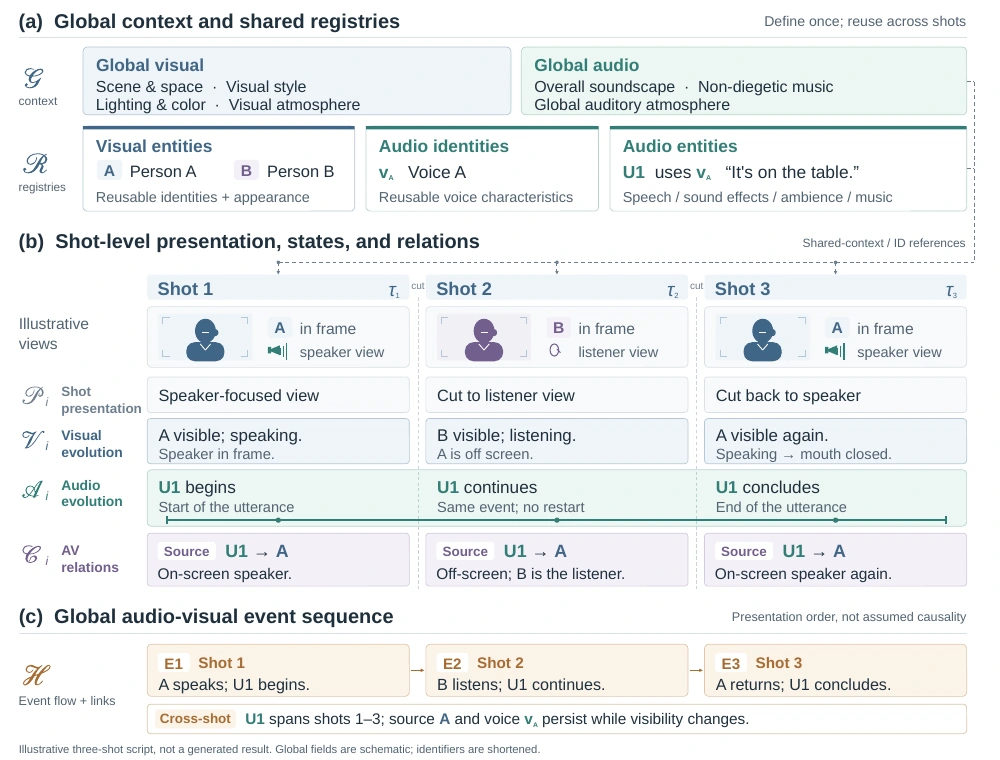
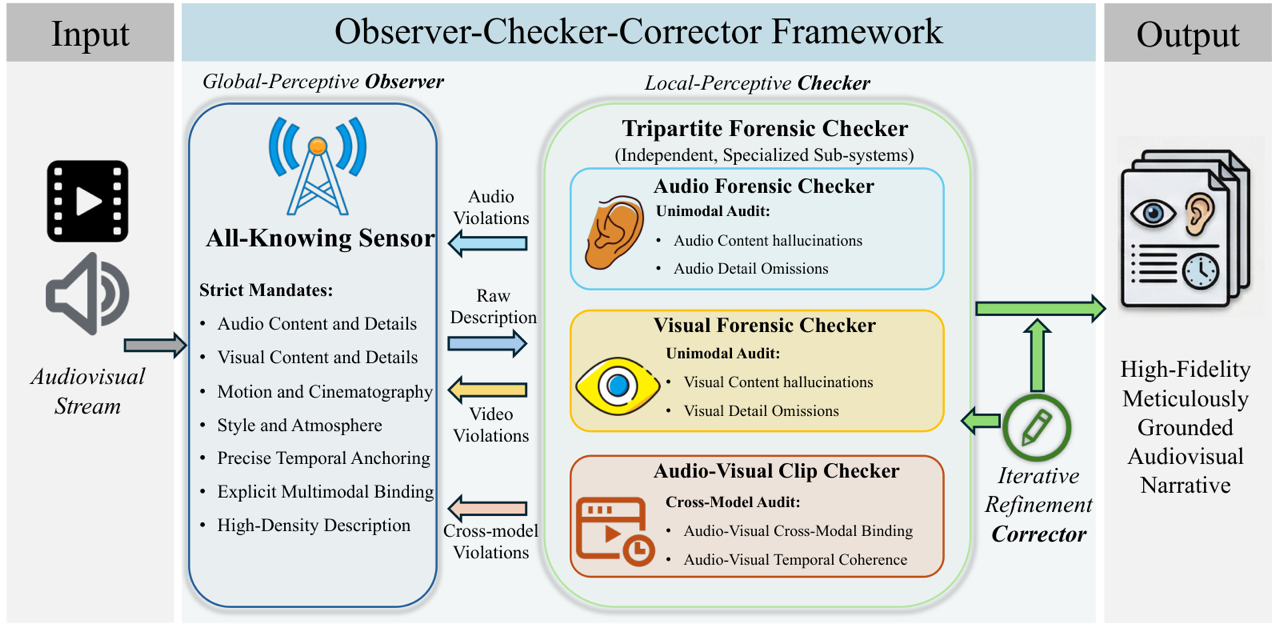
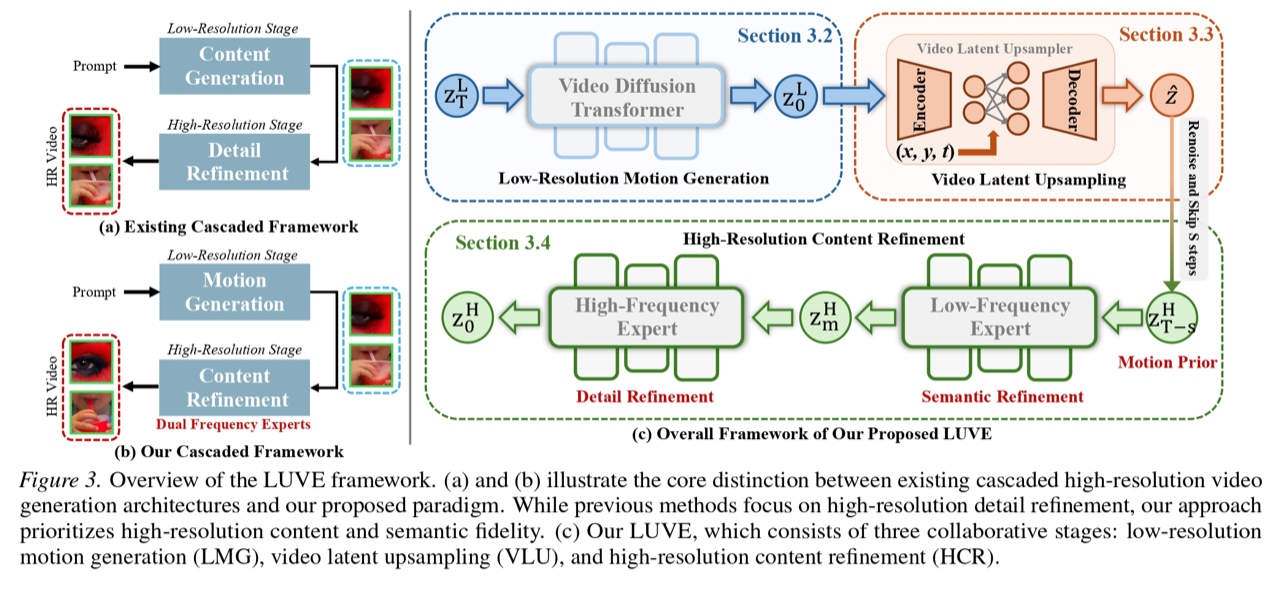
During my research internship at Meituan, I contributed to high-resolution video generation with a two-stage cascaded framework and to audiovisual captioning for multimodal pretraining. This work connects efficient generative modeling with fine-grained understanding of video and audio, supporting coherent, high-quality video synthesis.