Chen Zhao 赵晨

Ph.D. Student · Nanjing University · PCALab

I am a Ph.D. student in Computer Science and Technology at Nanjing University, advised by Prof. Ying Tai. I work in PCALab, led by Prof. Jian Yang.

My research focuses on visual generation, image restoration, and multimodal understanding. I am particularly interested in high-resolution image and video synthesis, frequency-aware modeling, and audiovisual captioning.

I am a research intern in Meituan's Beidou Talent Program (July 2025 – December 2026), where I have contributed to the LongCat video generation models and large-scale audiovisual data pipelines.

Chen Zhao
Chen Zhao · 赵晨
Nanjing University

Research Interests

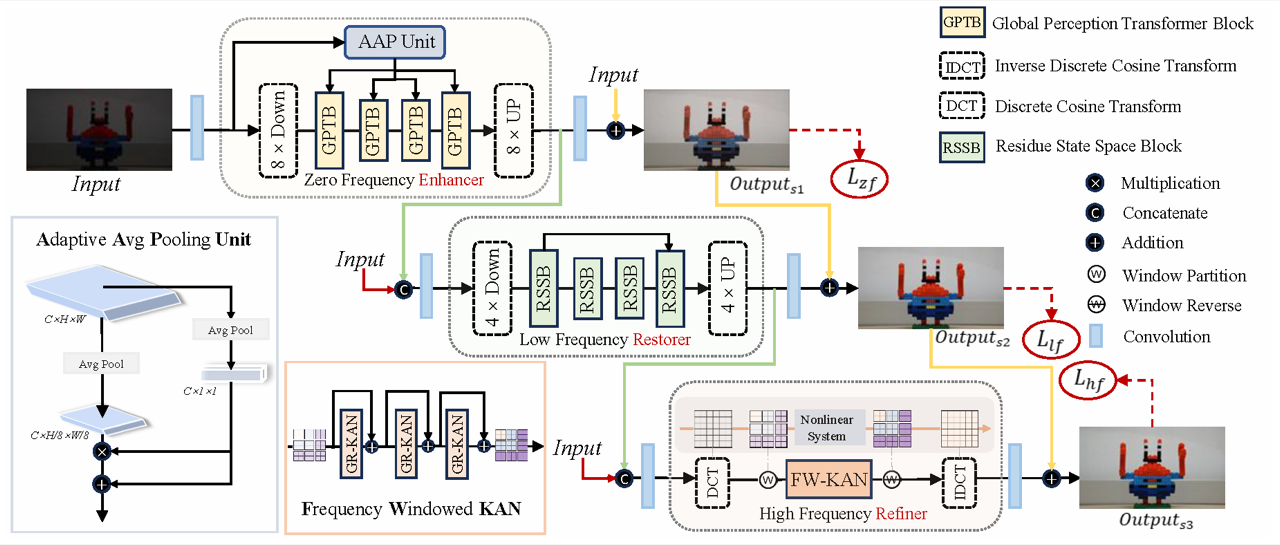
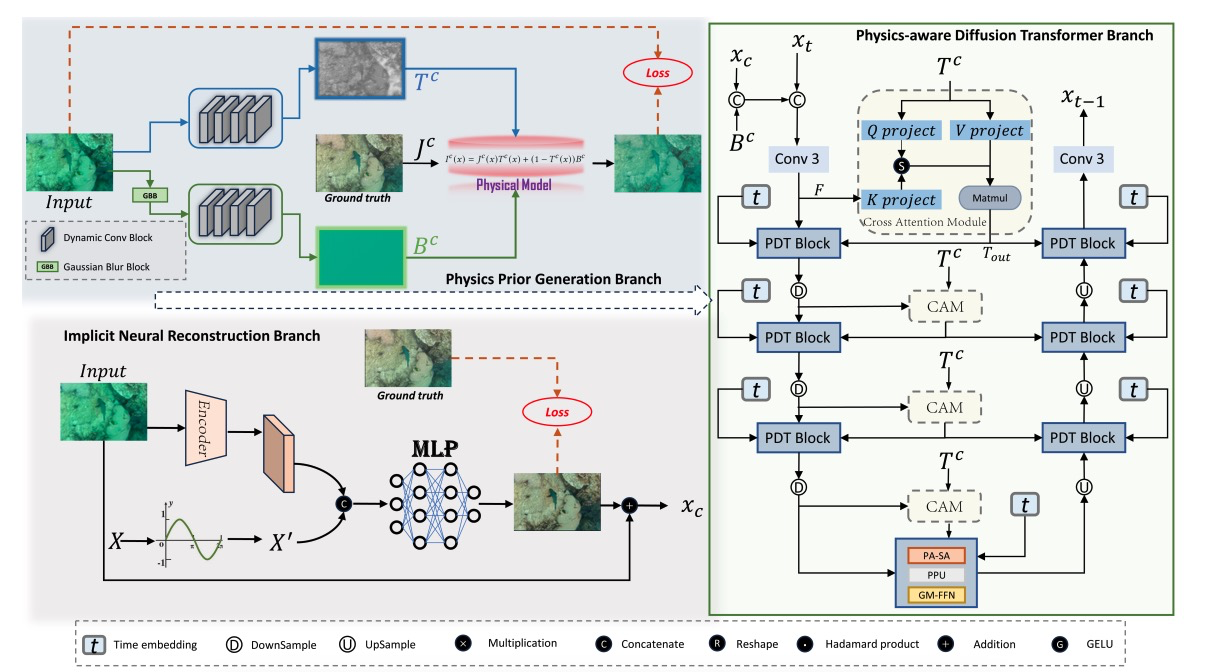
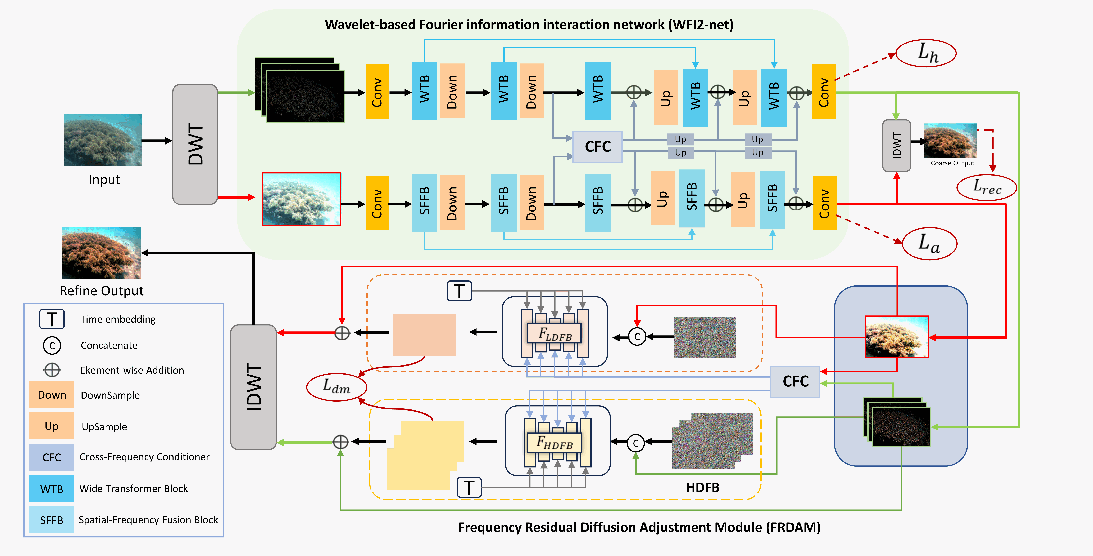
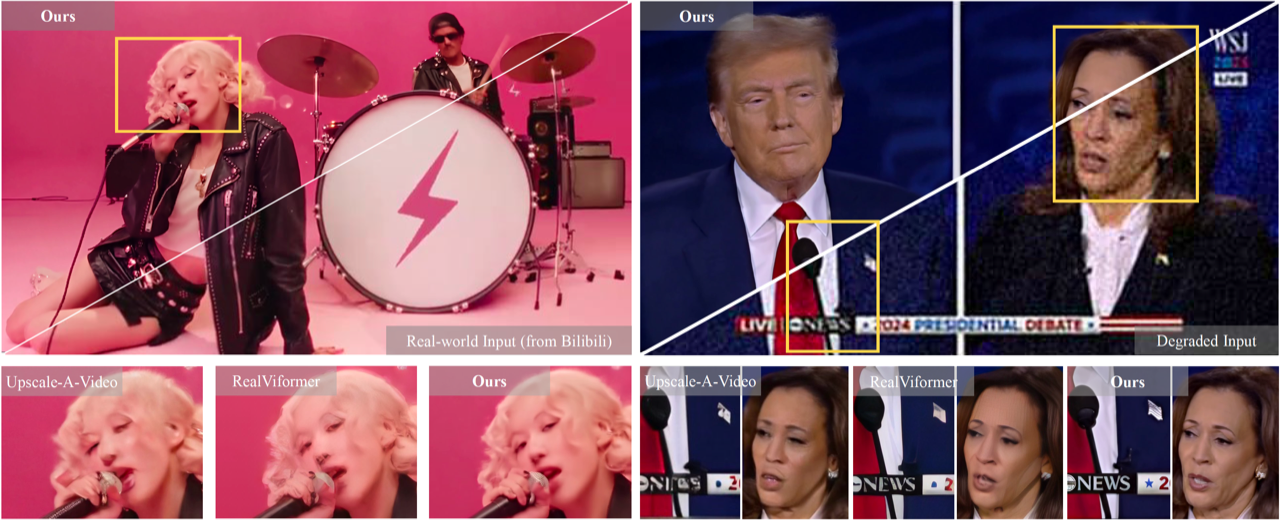
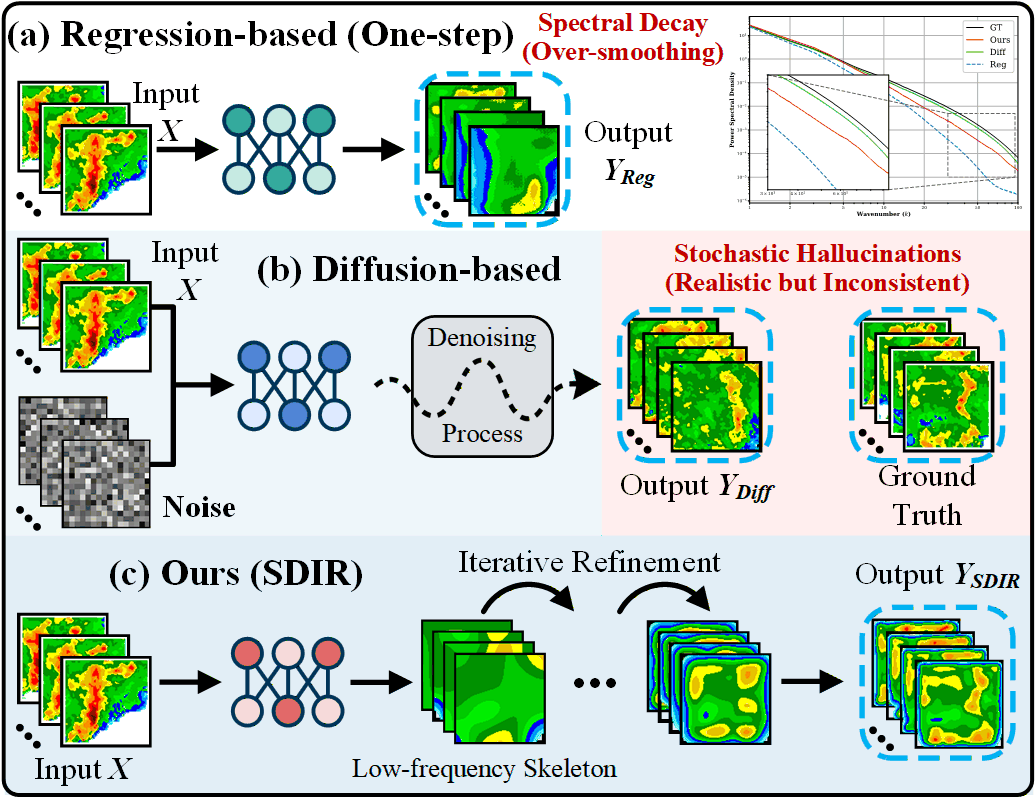
I study how to generate and recover visual content with faithful structure and fine detail. My work on high-resolution generation explores latent cascades, frequency-aware training, and high-quality datasets for image and video synthesis. In image restoration, I use spectral representations and generative priors to improve detail recovery at ultra-high resolutions.

I also work on audiovisual understanding, with a focus on aligning sound, visual content, and events over time. This connects my interests in multimodal captioning with the data pipelines that support video foundation models.

News

Selected for the CIE–Tencent Ph.D. Research Incentive Program (RMB 100,000), Hunyuan Large Model Track.
Our work on temporal and cross-modal alignment for audiovisual video captioning was accepted to ECCV 2026.
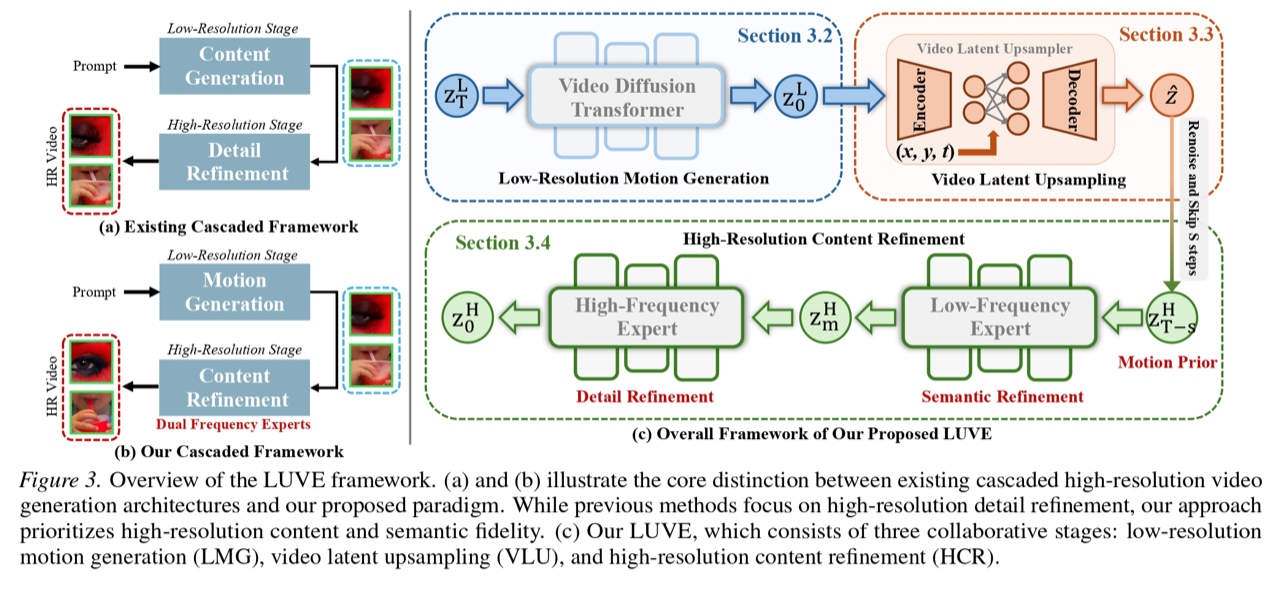
LUVE was accepted to ICML 2026, and our extended work on progressive spectral decoupling for UHD image restoration was accepted to IEEE TPAMI.
Received the National Scholarship for Doctoral Students at Nanjing University (RMB 30,000).
UltraHR-100K was accepted to NeurIPS 2025.

Projects

LongCat-Video

Meituan · Video Generation & Multimodal Pretraining

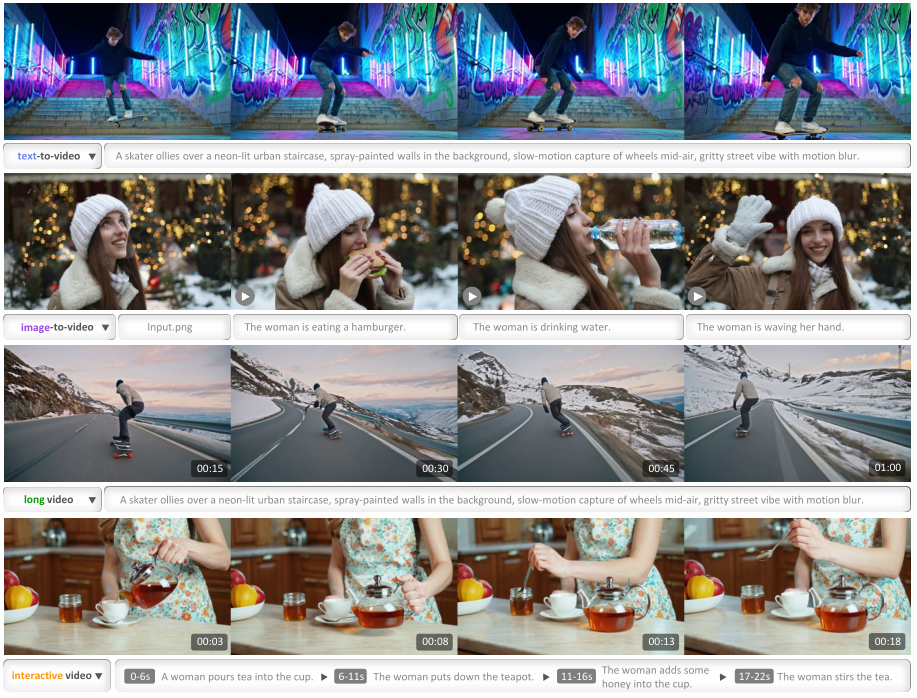
LongCat-Video is Meituan's unified foundation model for text-to-video, image-to-video, and video continuation.

During my research internship at Meituan, I contributed to high-resolution video generation with a two-stage cascaded framework and to audiovisual captioning for multimodal pretraining. This work connects efficient generative modeling with fine-grained understanding of video and audio, supporting coherent, high-quality video synthesis.
Selected Publications

Multimodal Generation & Understanding6 papers

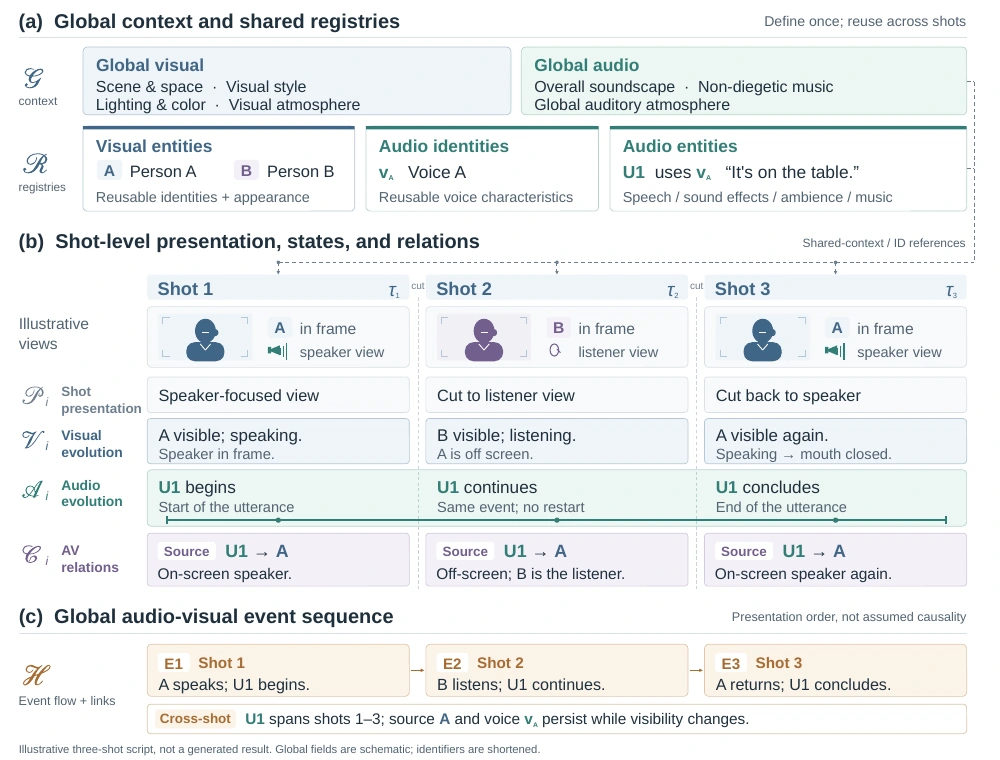
SSRS overview: persistent identities, shot-level states and relations, and a global audio-visual event sequence
Preprint 2026

Structured Stateful Relational Scripts with a High-Quality Dataset for Multi-Shot Audio-Visual Video Generation

Chen Zhao*, Lehan Shen*, Qilong Huang, Hongyu Li, Zhuoliang Kang, Xiaoming Wei, Jian Yang, Ying Tai

Preprint, 2026

Structured supervision and 100,000 curated clips for coherent multi-shot audio-visual generation.

Overview

Structured Stateful Relational Scripts make persistent identities, evolving states, sound-source bindings, and cross-shot event continuity explicit. MSAV-Script-100K provides 100,000 curated native multi-shot audio-visual clips with structured supervision. This work was carried out at Nanjing University and Meituan.

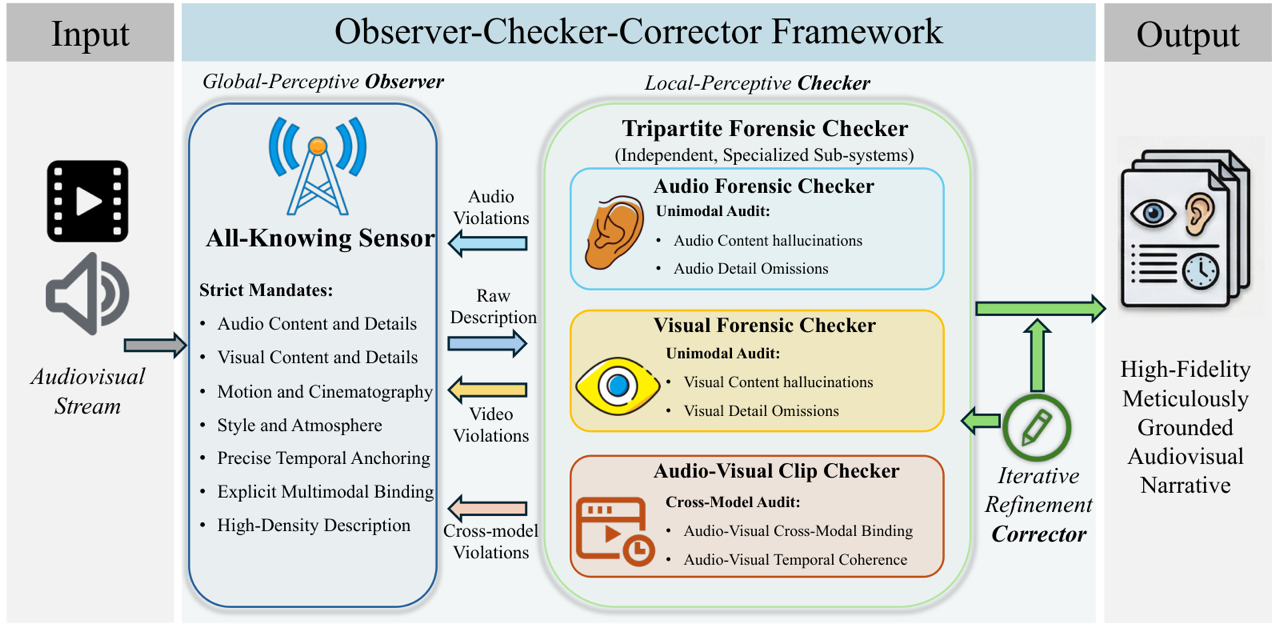
Research overview for Temporal and Cross-Modal Alignment for Enhanced Audiovisual Video Captioning
ECCV 2026

Temporal and Cross-Modal Alignment for Enhanced Audiovisual Video Captioning

Chen Zhao, Jiajun Ma, Qilong Huang, Tiehan Fan, Hongyu Li, Zhuoliang Kang, Xiaoming Wei, Jian Yang, Ying Tai

ECCV, 2026

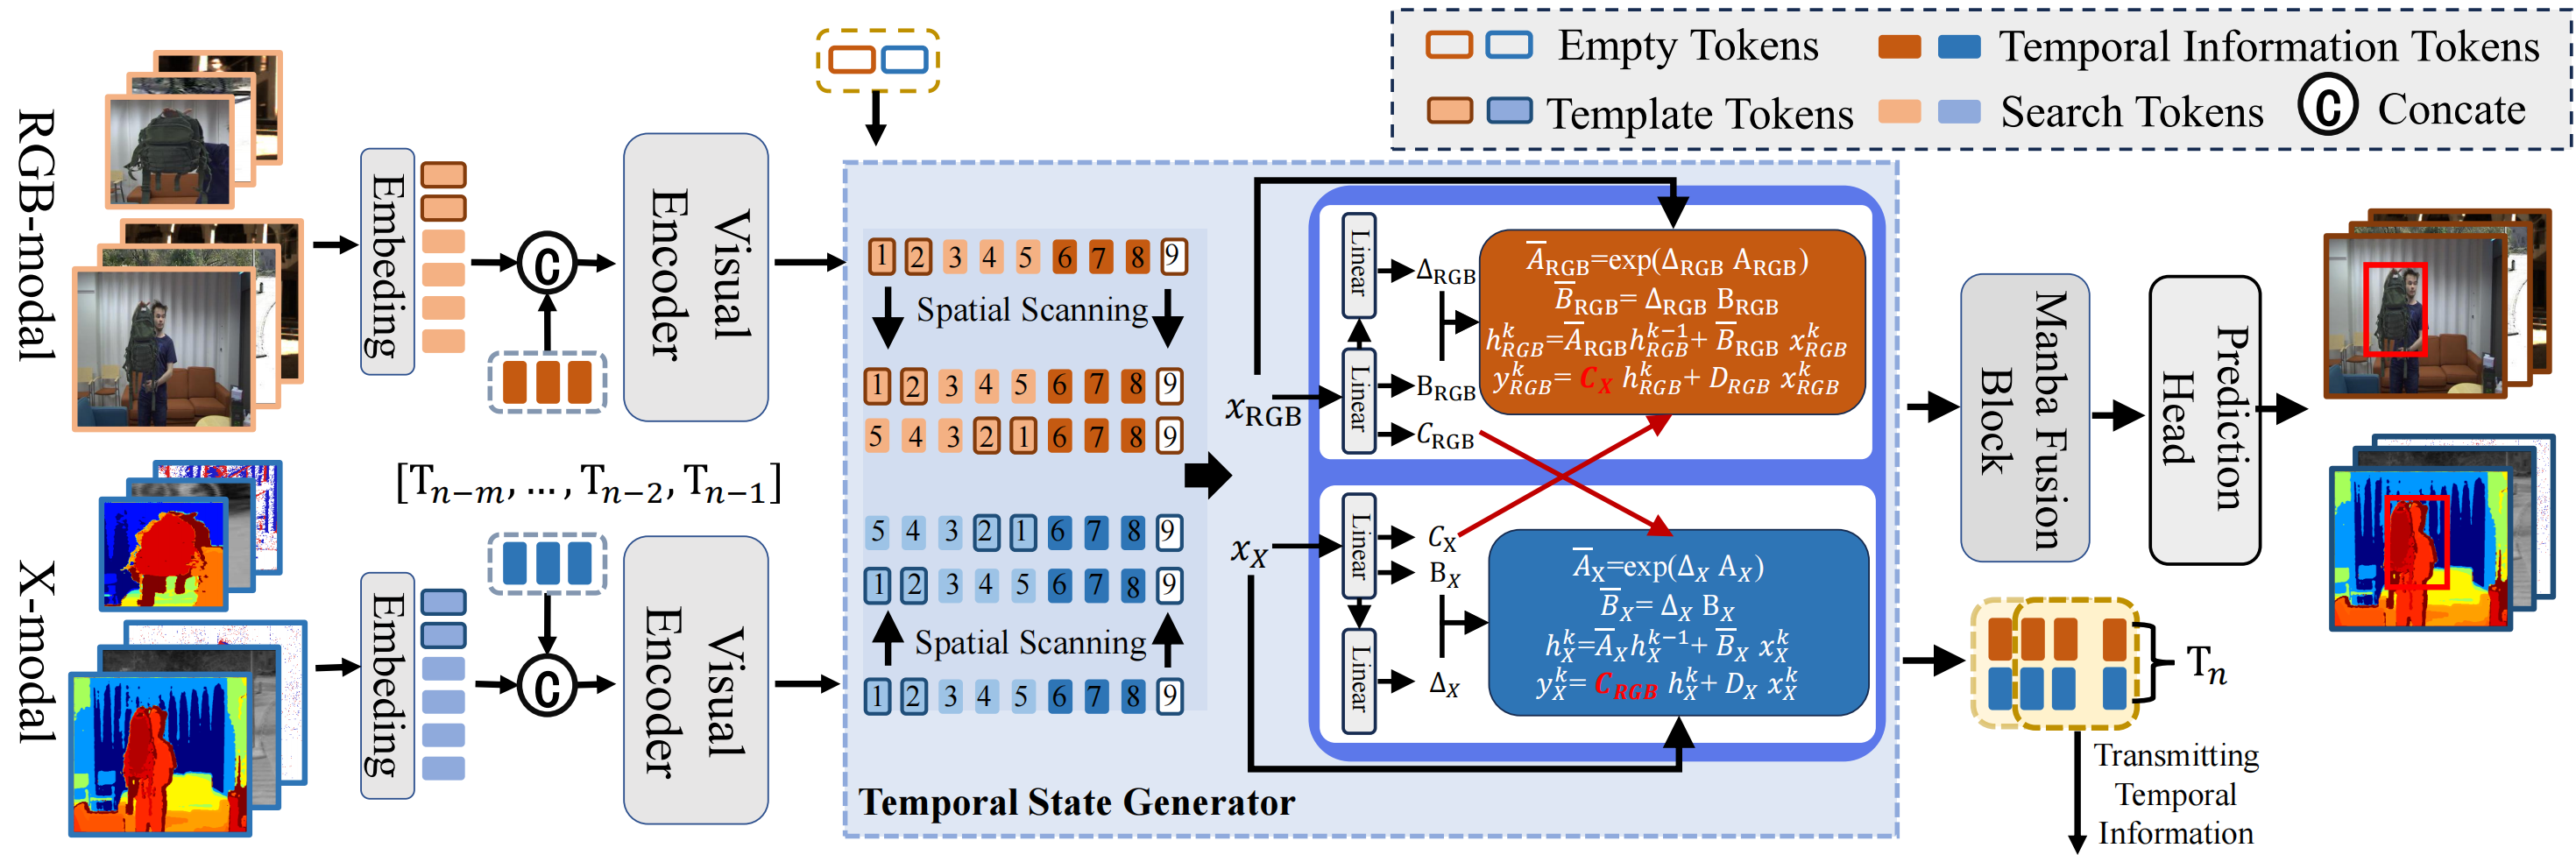
Audiovisual captioning with temporal and cross-modal alignment.

Overview

TCA-Captioner improves audiovisual captioning through iterative data refinement and a benchmark that evaluates audio-visual binding and temporal reasoning.

Research overview for Does FLUX Already Know How to Perform Physically Plausible Image Composition?
ICLR 2026

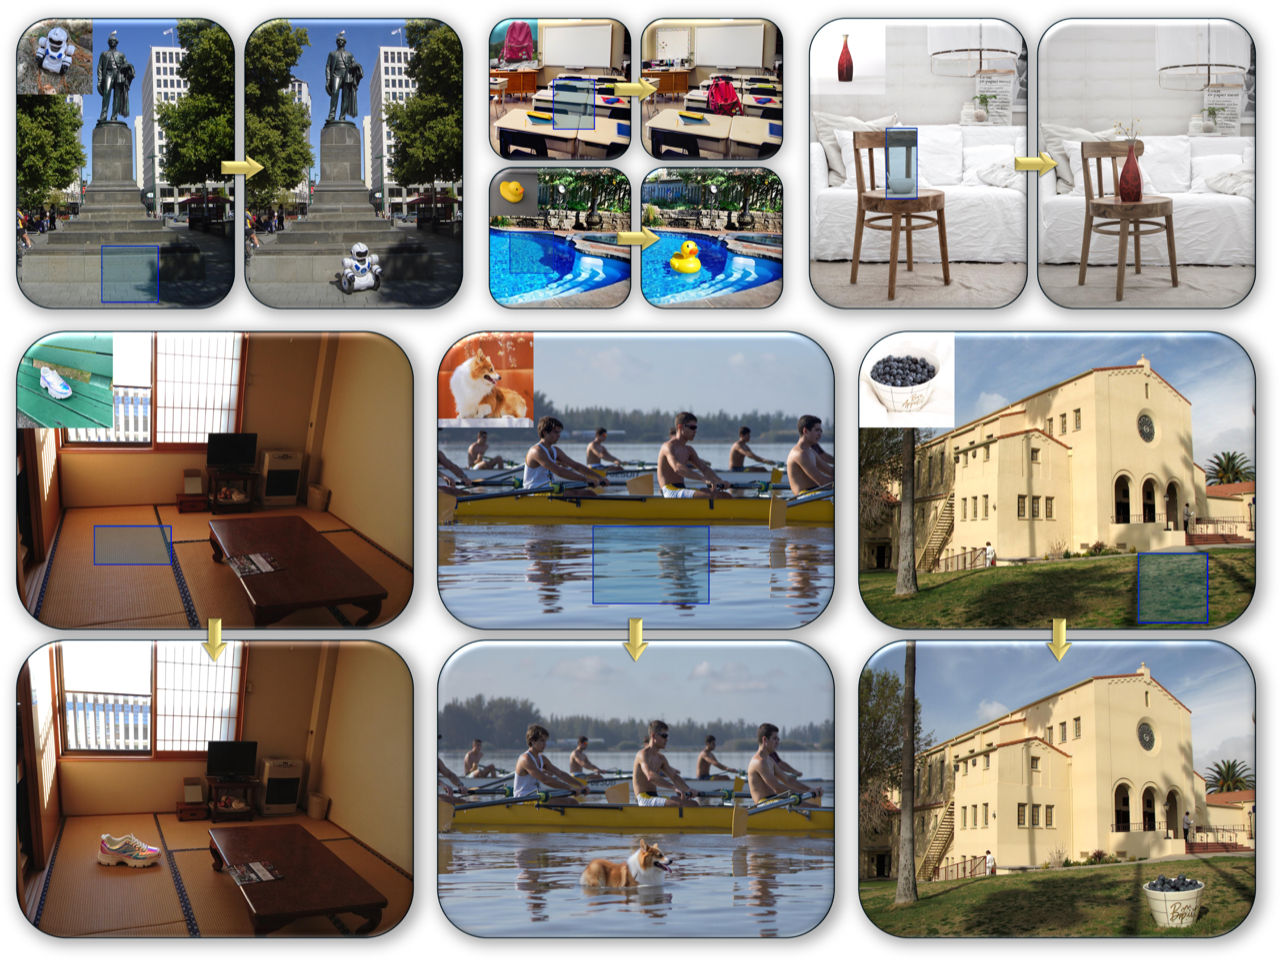
Does FLUX Already Know How to Perform Physically Plausible Image Composition?

Shilin Lu, Zhuming Lian, Zihan Zhou, Shaocong Zhang, Chen Zhao, Adams Wai-Kin Kong

ICLR, 2026

Training-free image composition using pretrained diffusion priors.

Overview

SHINE adapts pretrained diffusion priors for training-free image composition and introduces ComplexCompo to assess challenging lighting and reflection conditions.

Visual Restoration & Enhancement7 papers

Visual Super-Resolution3 papers

Other Research Areas3 papers

Education & Experience

Jul 2025 – Dec 2026

Meituan · Research Intern

Beidou Talent Program, Visual Generation Foundation Model Team

Worked on cascaded high-resolution video generation and audiovisual captioning for large-scale pretraining data. Related research includes LUVE (ICML 2026) and TCA-Captioner (ECCV 2026).

Sep 2024 – Present

Nanjing University · Ph.D. Student

Computer Science and Technology · PCALab

Advised by Prof. Ying Tai. Expected graduation: June 2028.

Honors & Awards

Academic Service

I have served as a reviewer for CVPR, ICLR, ICML, NeurIPS, AAAI, ICCV, ECCV, ACM Multimedia, and Pattern Recognition.

I received the CVPR 2025 Outstanding Reviewer Award.